

What a machine-learning model is, how it relates to the general idea of a model, and where large language models fit.
What are models in machine learning?
In machine learning, a model is the learned program that turns inputs into predictions or generated outputs.
It is a special case of a more general idea. In the ordinary sense, a model is a simplified representation that keeps selected relationships and leaves other details out.
A street map models a city for navigation. A weather forecast models how the atmosphere may change. A machine-learning model represents relationships found in data so that a computer can act on new cases.
The map is not the city. The learned model is not the world. Both are useful because they are selective.
How is this related to the philosophical idea of a model?
The article on Model asks what a model is in general: why it must leave things out, how it explains and predicts, when it can be wrong yet useful, and how overfitting and underfitting fail.
Those questions still apply here. A machine-learning model preserves patterns that helped on its training examples. It omits almost everything else about the situations those examples came from.
So this page does not replace that broader account. It asks what the word means inside machine learning, how such models are made, and how they are used in systems such as large language models.
How do they fit under machine learning?
Machine learning is a method for making a computer program in which data helps determine the rules the program follows.
People still choose the goal, the learning process, the data and the tests. Training then adjusts the model so that its behaviour better fits the examples or feedback.
In short:
Human-written learning process + training data → learned program (the model)
Later:
Model + new inputs → answers
Machine learning is the method. The model is what that method produces and later uses.
Is a machine-learning model the same as the program?
No, though they belong together.
The surrounding program receives data, runs training or inference, calls tools, checks outputs and presents results. The model contains the adjustable relationships learnt from data.
Two runs of the same training program can produce different models when the examples differ. The program provides the learning procedure. The model is what that procedure has learnt.
This is the same distinction drawn in the general account of a model: procedure and learnt representation are related, but not identical.
What does the model contain?
Usually not a neat list of human-readable rules, and not a book of facts with clear source notes.
It contains parameters: large numbers of values that shape how an input is turned into an output. Training adjusts those values.
Together they encode statistical regularities found in the training data. That is why a model can be fluent or accurate on familiar kinds of case, and still fail on a new one.
What kinds of machine-learning model are there?
Models differ by what they are built to handle and by how they are structured:
- Classifiers — assign an input to a category, such as spam or not spam.
- Regressors — predict a quantity, such as a price or a temperature.
- Vision models — work with images or video, for example recognising objects.
- Language models — predict and generate text; large language models are the scaled form used in many assistants.
- Other generative models — produce images, audio or other structured outputs from a prompt or a latent description.
The forms differ, but each is still a selective representation trained for a purpose.
When is a model useful, and when is it misleading?
A model can be wrong in detail and still useful within a limited range. A flat map is not a complete description of the Earth, yet it helps you walk across a neighbourhood.
The same caution applies to machine learning. A model that matches its training data closely may still fail on new cases if it has fitted accidents rather than the wider pattern. That failure is overfitting. A model that is too simple to capture an important pattern underfits.
Useful questions are therefore practical:
- Purpose — What decision or prediction is this model for?
- Evidence — What data shaped it, and what was left out?
- Range — Under what conditions has it been tested?
- Check — How will a wrong answer be noticed before it causes harm?
What belongs in this section?
This section gathers notes on learned models inside machine learning.
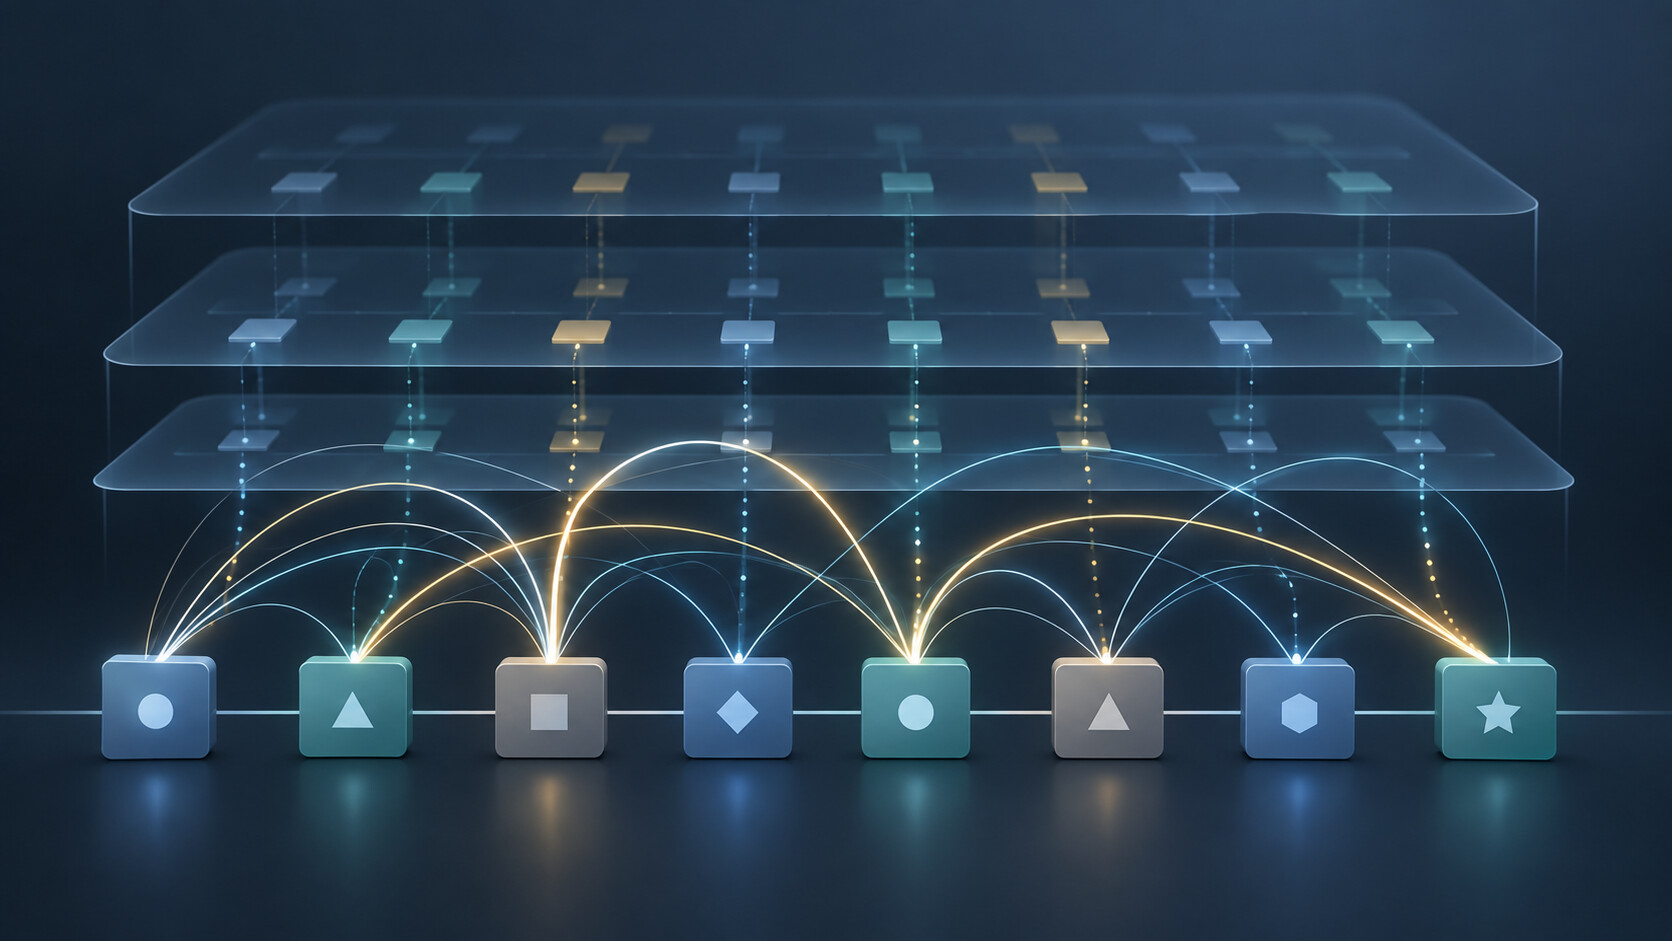
It begins with large language models and Transformers. An LLM is a kind of model; a Transformer is an architecture used to build many LLMs. Related pages under artificial intelligence and machine learning describe the wider methods those models depend on.
For the general idea of representation, prediction, explanation and the limits of any model, start from Model.
Ai disclosure: written with the help of AI (ChatGPT & Grok). You are encouraged to point out errors and omissions.